How AI Search Engines Generate Answers: Retrieval, Ranking and Citation
AI search is changing how people discover information, compare businesses, evaluate products, and make purchasing decisions. Instead of displaying only a list of blue links, modern AI-powered search experiences can interpret a question, retrieve relevant information, compare sources, generate a conversational response, and provide citations that direct users to supporting webpages.
For marketers, SEO professionals, and business owners, this shift raises an important question: How do AI search engines decide which information to use, which sources to prioritise, and which websites to cite in their answers?
The answer involves several interconnected processes: query understanding, information retrieval, ranking, context assembly, answer synthesis, and citation selection. Each process influences how information moves from a user’s question to the final response.
Understanding this workflow is essential for businesses that want to improve their visibility in Google AI Overviews, Google AI Mode, ChatGPT search, Perplexity, and other AI-powered discovery experiences. Although these platforms use different architectures and selection mechanisms, they share a common challenge: identifying useful information and presenting it in a form that helps users accomplish their goals.
This guide explains how AI search engines generate answers, how retrieval and ranking differ, why some websites receive citations while others do not, and how businesses can adapt their SEO, Answer Engine Optimisation (AEO), and Generative Engine Optimisation (GEO) strategies for this evolving search environment.
How AI Search Engines Generate Answers
Traditional search engines primarily help users discover information by presenting a ranked list of webpages. Users enter a query, review the available results, open relevant pages, and assemble an answer themselves.
AI search changes this interaction by generating a response that may combine information from multiple sources. Instead of requiring users to visit several webpages before understanding a topic, an AI search system can summarise relevant information, explain relationships, compare alternatives, and provide references to supporting sources.
For example, someone searching for “How can a Dubai e-commerce business improve its online visibility?” might receive an AI-generated response covering technical SEO, product-page optimisation, paid advertising, local search visibility, and conversion optimisation. The response may include links to sources that support different parts of the explanation.
However, an AI-generated answer is not necessarily produced by one model independently recalling information. In many search experiences, external retrieval systems help identify information that can be used to construct the response. The exact process varies by platform, query type, and product configuration.
From Search Queries to AI-Generated Responses
The answer-generation process begins when a user submits a question. The system must interpret what the user means, identify the information needed to answer it, and determine whether external sources should be retrieved.
Consider the question:
“What is the best digital marketing strategy for a luxury fashion brand in Dubai?”
This question contains several connected requirements:
- Industry: Luxury fashion.
- Location: Dubai and the wider UAE market.
- Objective: Developing an effective marketing strategy.
- Potential subtopics: Brand positioning, paid advertising, influencer partnerships, search visibility, customer retention, and premium customer experience.
An AI search system may interpret these elements as related information needs rather than treating the question as a simple keyword-matching exercise.
Depending on the system, it might search for luxury consumer behaviour, regional marketing trends, successful fashion campaigns, and relevant agency expertise. The retrieved information can then provide evidence for different parts of the final answer.
The language model helps interpret and express the response, while retrieval and ranking components may help determine which external information is available to the model.
The Main Components of an AI Search Engine
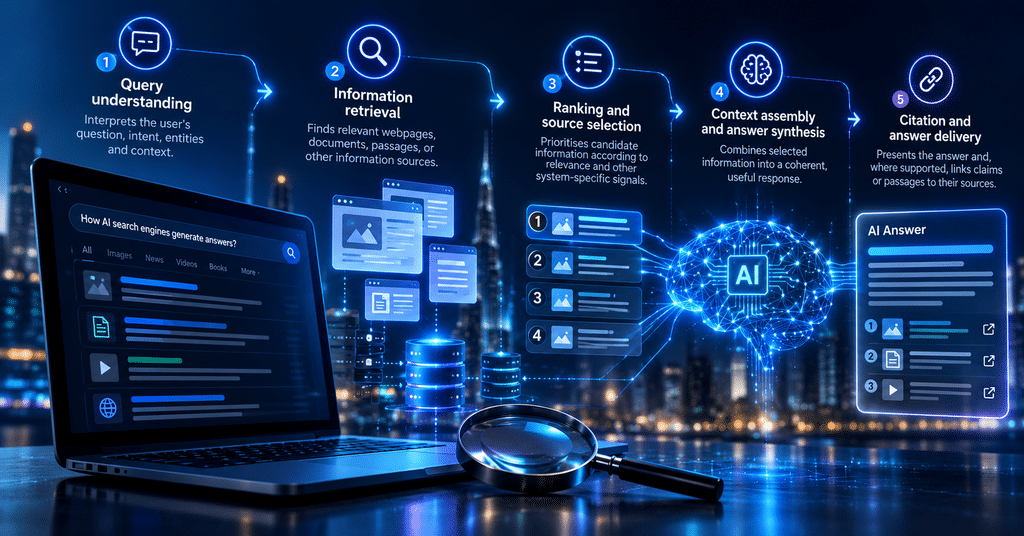
Although implementations differ, AI-powered search experiences typically involve several connected components that work together to generate answers. Query understanding interprets the user’s question, intent, entities, and context to determine what information is needed. Information retrieval identifies potentially relevant webpages, documents, passages, and other information sources. Ranking and source selection prioritise candidate information according to relevance and other system-specific signals. Next, context assembly and answer synthesis combine selected information into a coherent, useful response. Finally, citation and answer delivery present the answer and, where supported, link claims or passages to their sources.
This is a simplified conceptual model, as actual AI search systems may combine, repeat, reorder, or omit individual stages. These components are also interconnected rather than completely independent. For example, a system may retrieve additional sources after identifying gaps in the initial results, rewrite a query to explore a different angle, or conduct another retrieval round before generating the final answer.
Traditional Search vs AI Search: What Changes?
Traditional search and AI search share many underlying information-discovery principles, but they present and use information differently.
| Aspect | Traditional search | AI-powered search |
| Main output | Ranked links and search features | Generated answers, often with links |
| Query interpretation | Keywords, intent, entities, and context | Similar signals, potentially expanded into multiple information needs |
| Information retrieval | Finds relevant documents and pages | May retrieve pages, passages, and other evidence for answer generation |
| Source selection | Ranks results for the search interface | May rank and select sources specifically for the generated response |
| Answer creation | Primarily performed by the user | Language models may synthesise retrieved information |
| Citation behaviour | Displays links to search results | May associate sources with individual claims or answer sections |
| User interaction | Often involves visiting several pages | Can resolve some questions directly within the search interface |
The distinction is not absolute. Traditional search engines already use sophisticated ranking and language understanding, while AI search experiences can continue to display conventional organic results.
The important difference is that AI search introduces an additional layer: information must not only be discoverable but may also need to be selected, interpreted, synthesised, and attributed within a generated answer.
For businesses, this means that achieving a strong organic ranking remains valuable, but it does not automatically guarantee inclusion in an AI-generated response.
Step One — Query Understanding and Query Fan-Out
Before an AI search engine can retrieve useful information, it must establish what the user is asking and what kind of evidence would help answer the question.
A short question may express a straightforward need, while a longer question can contain several connected requirements. Query understanding helps the system interpret these requirements and identify relevant search paths.
How AI Search Interprets User Intent
Search intent describes the underlying purpose of a query. Two users may use similar words while expecting different answers.
For example:
- “What is search engine optimisation?” indicates an informational need.
- “Best SEO agencies in Dubai” indicates commercial investigation.
- “SEO agency pricing in Dubai” suggests that the user is comparing costs.
- “Hire an SEO agency for my online store” indicates a more direct purchasing intention.
AI search systems may use the wording of a question, surrounding conversational context, recognised entities, and other available signals to interpret intent.
The system also needs to understand relationships between concepts. A search for “best SEO strategy for a luxury watch retailer” involves more than the general meaning of SEO. It introduces a specific industry, a commercial objective, and potentially a high-value audience.
This interpretation can influence which sources are retrieved. A general educational article might help explain SEO fundamentals, but a detailed case study about luxury e-commerce could provide more relevant evidence for a question about luxury retail strategy.
For content marketers, the implication is straightforward: content should address the user’s actual information need, not merely repeat the target keyword.
A page targeting “AI SEO services” should explain the service, its applications, its limitations, its benefits, and how businesses can evaluate potential providers. Simply repeating the phrase throughout the article does little to answer the questions a prospective customer may have.
What Is Query Fan-Out in AI Search?
Query fan-out is a process in which a complex search request is expanded into multiple related searches or sub-queries.
Rather than relying on one broad search, a system may explore several narrower questions that collectively help answer the original request. This can expand the range of information considered during retrieval.
Imagine a user asks:
“How can a small e-commerce business use AI to improve marketing performance?”
Depending on the search system, its query planning may explore questions such as:
- How is AI used in e-commerce marketing?
- Which AI tools support product recommendations?
- How can AI improve paid advertising?
- What are the applications of AI in customer segmentation?
- How can businesses measure AI marketing ROI?
- What are the privacy and implementation risks of AI marketing?
Query fan-out is particularly useful when a question requires information from different sources. One webpage may explain advertising optimisation, another may describe personalisation, and a third may provide research on customer behaviour.
The final answer can combine these perspectives into one response.
However, query fan-out does not mean every AI search engine always generates the same number of sub-queries or uses an identical procedure. Query planning differs between platforms and can change according to the complexity of the question.
How Query Fan-Out Changes SEO and Content Strategy
Traditional keyword strategies often focus on identifying a primary keyword and creating a page designed to rank for it. That approach remains useful, but AI search creates an additional reason to understand the broader network of questions associated with a topic.
Consider an article targeting “AI SEO for e-commerce”. A comprehensive resource could cover:
- Product-page optimisation.
- Structured data and product attributes.
- Technical crawling and indexing.
- Product descriptions and factual accuracy.
- Customer reviews and trust signals.
- AI-generated shopping experiences.
- Measuring organic and AI referral performance.
These subtopics address different aspects of the same subject. A well-organised article can help readers understand the topic while making relevant passages easier to identify and interpret.
This does not mean every article should cover every related keyword. Excessive breadth can make a page unfocused. The goal is to cover the concepts necessary to satisfy the intended audience.
A practical approach is to build a question map before writing:
- Identify the main question the page must answer.
- List the natural follow-up questions a reader may ask.
- Group related questions into logical sections.
- Add evidence, examples, or explanations where they materially improve the answer.
- Link to separate resources when a subtopic deserves deeper treatment.
For example, an article on query fan-out can link to a separate guide explaining retrieval-augmented generation, while an article about AI citations can link to a guide about training data versus live retrieval.
This creates a connected content ecosystem rather than a collection of isolated keyword-targeted articles.
Step Two — Retrieval: How AI Search Finds Information
Once the system has interpreted the query and determined what information it needs, the next challenge is finding suitable sources.
This is the retrieval stage. It involves identifying potentially relevant documents, webpages, passages, or other information that may help answer the user’s question.
Retrieval is important because a language model cannot cite an external webpage it has not accessed through an appropriate information pathway. Whether a specific page can be retrieved depends on the platform’s capabilities, available indexes, query process, permissions, and other technical factors.
What Is Information Retrieval?
Information retrieval is the process of finding relevant information from a collection of documents or data.
Traditional search engines use retrieval systems to locate webpages from their indexes. AI-powered search can build on similar techniques while using additional methods to identify passages that relate closely to a question.
Suppose a user asks:
“What is the difference between SEO, AEO, and GEO?”
A retrieval system may identify pages that discuss all three concepts, pages focused specifically on Answer Engine Optimisation, and pages that compare search optimisation approaches.
The system does not necessarily need to retrieve an entire webpage for every query. It may identify particular passages, snippets, or sections that contain relevant information.
This distinction matters because a page can be broadly relevant while containing only a small section that directly answers the question.
For content creators, making important information easy to locate is therefore valuable. Clear headings, focused paragraphs, descriptive terminology, and well-organised explanations can help people and automated systems understand a page’s subject matter.
How AI Search Retrieves Web Content
Several techniques can contribute to information retrieval. The exact combination depends on the search engine.
Crawling and indexing: Search systems may discover webpages through crawling, process their content, and store representations in searchable indexes. A page that cannot be accessed or indexed may be unavailable to a particular retrieval pathway, although some platforms use other sources and access mechanisms.
Keyword-based retrieval: Terms appearing in the query and document can help identify potentially relevant information. Exact terminology remains important, especially for product names, technical concepts, and named entities.
Semantic retrieval: Systems can also use meaning and contextual similarity to find relevant information even when the page does not repeat the user’s exact wording.
Vector search: Some systems represent text as numerical embeddings and compare these representations to identify semantically related content. This can help surface relevant passages that use different vocabulary from the original question.
Entity-based retrieval: Recognising people, organisations, products, locations, and their relationships can help systems identify information about a specific subject.
These approaches are complementary rather than interchangeable. A search system may combine lexical matching with semantic retrieval, metadata, ranking models, and other signals to generate candidate results.
Understanding Keyword Search and Semantic Search
Keyword search focuses on the words and terms present in a query and in available documents. Semantic search attempts to capture meaning, context, and relationships between concepts.
For example, consider these two queries:
- “How to reduce shopping cart abandonment.”
- “Why do online customers leave before completing checkout?”
The wording differs, but both questions concern a similar problem. A semantic retrieval system may identify overlapping resources even if a webpage primarily uses one phrase rather than the other.
This is one reason natural, descriptive writing can be more useful than rigid keyword repetition.
A page about checkout optimisation can naturally discuss payment friction, unexpected delivery charges, account creation, slow loading, and unclear return policies. These concepts provide context for the subject and help readers understand its practical implications.
However, semantic retrieval does not eliminate the value of precise terminology. If an article explains retrieval-augmented generation, explicitly using the recognised term and its abbreviation, RAG, helps establish what the article covers.
The best approach combines precise language with meaningful explanations.
What Are Vector Embeddings, and Why Do They Matter?
Vector embeddings are numerical representations of information. Depending on the model and method used, these representations can capture aspects of the meaning or characteristics of text, images, and other data.
In a text retrieval system, a question and a document passage may each be converted into vectors. The system can then compare their representations to estimate how closely they relate.
For example, a query about “improving product discoverability in AI search” might be semantically related to passages discussing product data quality, product schema, product feeds, and search visibility.
The vocabulary does not need to be identical for the passages to be potentially relevant.
Yet vector similarity is not the same as factual verification. A passage can be semantically similar to a query without providing a correct or sufficiently supported answer. Ranking, source evaluation, and other stages may therefore remain important.
For SEO professionals, the practical takeaway is to create content that explains concepts and relationships clearly rather than attempting to manipulate an assumed embedding score.
What Is Retrieval-Augmented Generation (RAG)?
Retrieval-augmented generation, commonly abbreviated as RAG, is an approach that combines information retrieval with language-model generation.
In a typical RAG workflow, a system retrieves relevant external information and provides it as context to a language model. The model then generates a response using the available context and its learned capabilities.
A simplified process looks like this:
- A user asks a question.
- The system searches an available knowledge source.
- Relevant documents or passages are retrieved.
- Selected information is provided to the language model.
- The model generates an answer informed by that context.
For example, an organisation could use RAG to answer questions about its product catalogue. Rather than relying solely on a model’s general training knowledge, the system retrieves product specifications, pricing information, and support documentation from an approved knowledge base.
In web search, retrieval can provide external information that helps answer questions about current events, products, services, and other topics.
However, not every AI search engine uses the same RAG architecture, and not every generated answer follows a single standard retrieval pipeline. Some systems combine multiple retrieval rounds, specialised ranking components, tool use, or other mechanisms.
RAG also does not automatically guarantee accuracy. The retrieved material may be incomplete, outdated, contradictory, or incorrect. The language model can still misinterpret evidence or produce unsupported statements.
Training Data vs Live Retrieval
One of the most important distinctions in AI search is the difference between information learned during model training and information obtained through retrieval at query time.
A language model is trained on large collections of data to learn statistical patterns, language relationships, and other capabilities. Its learned parameters can encode useful general knowledge, but this does not mean the model has a live, searchable copy of every webpage.
Live retrieval is different. A connected search system can obtain external information from available sources when responding to a question.
| Factor | Training knowledge | Live retrieval |
| Information source | Data used during model training | External documents or data accessed at query time |
| Freshness | May not reflect recent changes | Can reflect current information if the source is available and retrieved |
| Source attribution | Specific training sources may not be identifiable | Retrieved sources can potentially be linked or cited |
| Main limitation | Knowledge can be incomplete or outdated | Retrieval can miss relevant sources or surface unreliable material |
| Typical role | General language and background knowledge | Additional evidence and information for a particular query |
Imagine a user asks for the current pricing of a software subscription.
A model’s learned knowledge might contain historical information, but the price could have changed. A search-connected system may retrieve the vendor’s current pricing page and use it to construct a more relevant response.
The retrieved page still needs to be interpreted correctly. The price may vary by region, plan, currency, or billing period.
This distinction is important for businesses. Publishing information online does not guarantee that every AI model will learn it immediately. Search-connected systems may discover the information through retrieval, while model training and other knowledge pathways operate differently.
Why Some Webpages Are Retrieved While Others Are Not
A webpage may fail to appear in a generated answer for several reasons.
Technical accessibility: The page may be blocked, unavailable, incorrectly canonicalised, or difficult for a search system to process.
Relevance: The page may not sufficiently address the user’s question or one of its sub-queries.
Content clarity: Important information may be buried in long paragraphs, presented ambiguously, or hidden behind interfaces that are difficult to access.
Source coverage: Other pages may provide more specific evidence or better explain the requested subject.
Freshness: For time-sensitive queries, a current source may be more useful than an outdated one.
Retrieval limitations: The system may simply fail to discover or select a relevant page for that particular request.
A technically accessible webpage can still be excluded from a particular answer. Likewise, a page that performs well in organic search may not be retrieved for every AI query.
Businesses should therefore start with the fundamentals: maintain accessible pages, publish genuinely useful content, use accurate metadata, establish clear internal links, and make important information available in readable text.
These actions support discoverability, although none guarantees AI retrieval or citation.
Step Three — Ranking: How AI Search Chooses Relevant Sources
Retrieval identifies potential sources, but not every retrieved document deserves equal consideration. A search system needs a way to prioritise information according to its usefulness for the user’s question.
This is where ranking and source selection become important.
In conventional search, ranking determines the order in which search results are presented. In AI-powered search, ranking can also influence which documents or passages are selected to support a generated answer.
These are related but distinct tasks. The source that ranks highest in the conventional search results is not necessarily the source that best supports every part of an AI-generated response.
What Does Ranking Mean in AI Search?
Ranking is the process of ordering candidate results according to their estimated relevance or usefulness.
Imagine that an AI search system retrieves ten webpages in response to a question about e-commerce conversion optimisation. Some discuss conversion strategy generally, while others contain detailed evidence about checkout abandonment, product-page usability, and payment friction.
A ranking process can help prioritise the sources that most closely match the information requirements.
Depending on the implementation, ranking may take place at multiple stages:
- Initial retrieval ranking identifies promising documents.
- A subsequent ranking stage may assess a smaller set of candidates in greater detail.
- Passage-level selection may identify the most useful sections within retrieved documents.
- Additional selection mechanisms may determine which sources are included in the generated answer.
Not every platform uses all these stages, and their order can vary.
The central principle is that retrieval determines what information is available for consideration, while ranking helps determine what information is prioritised.
For website owners, this distinction explains why simply getting a page indexed does not guarantee that it will become a prominent source in an AI answer.
Key Factors That May Influence AI Source Selection
The exact ranking mechanisms used by commercial AI search platforms are not fully public. It would therefore be inaccurate to claim that all platforms evaluate webpages using one universal set of factors.
Nevertheless, several qualities are useful to consider when creating content intended to answer questions accurately.
Relevance to the user’s question
A source should address the actual information need rather than merely mention the same keywords.
For example, a comprehensive guide to general digital marketing may be less useful for a question about the technical requirements of product structured data than a focused technical guide.
Content quality and completeness
Content should provide enough information to answer the question meaningfully. A page that explains a concept, demonstrates how it works, and discusses its limitations may be more useful than one containing only a brief definition.
Completeness does not necessarily mean greater length. A concise, accurate explanation can be more useful than a long article filled with repetition.
Reliability and supporting evidence
Factual claims are easier to evaluate when they are supported by credible sources, transparent methodology, original research, or verifiable documentation.
For instance, a statement about a search engine’s technical requirements is better supported by official documentation than by an unsupported claim on a marketing blog.
Freshness and accuracy
Current information can be particularly important for pricing, product specifications, regulations, software features, and recent developments.
However, freshness is not universally decisive. An authoritative historical explanation may remain more useful than a recently published page that provides little evidence.
Clarity and extractability
Clear headings, descriptive paragraphs, and focused explanations help readers identify the information they need. They also create a more understandable structure for automated content-processing systems.
These qualities should be treated as sound content and information-design practices, not as a guaranteed formula for ranking in AI search.
How AI Search Evaluates Multiple Sources
Many questions require evidence from several sources rather than one comprehensive webpage.
Consider the question:
“Is AI marketing automation worth the investment for a small business?”
A useful answer may need information about:
- The types of marketing tasks that can be automated.
- The costs of implementing and maintaining the tools.
- Potential productivity improvements.
- Risks involving data privacy and output accuracy.
- How businesses can measure returns.
A software vendor might provide accurate information about its features and pricing. An independent case study might explain implementation outcomes. Official regulatory guidance might clarify relevant data-protection obligations.
These sources serve different purposes. The vendor is well placed to document its own product features, while an independent study may provide stronger evidence about broader outcomes.
An AI search system may retrieve and prioritise complementary sources to address different parts of the question.
However, retrieving multiple sources does not guarantee that the final response will represent them fairly. The system may overlook important qualifications, misinterpret statistics, or combine claims that apply under different circumstances.
This is why source diversity and factual accuracy matter, and why users should check important claims against the cited material.
Why Lower-Ranking Pages Can Appear in AI Answers
One common misconception is that AI search must cite the page ranking first in conventional organic results.
In practice, a page’s organic position and its usefulness for a generated answer are not identical measurements.
Suppose a user asks:
“What is query fan-out, and how should an SEO team respond to it?”
A broad SEO guide might rank highly for the general topic of AI search. However, a specialised article about query fan-out could provide a more direct explanation of how complex questions may be expanded into related searches.
If the system retrieves that specialised article and determines that it supports the answer, the article may be cited even if it has a lower organic ranking for the original query.
Several mechanisms can explain this outcome:
- Different information needs: The system may retrieve sources for several sub-queries, each with a different set of relevant pages.
- Different selection stages: The pages considered for an AI answer may not be identical to the conventional organic results shown for the original question.
- Passage-level relevance: A specific section can answer one part of a question particularly well.
- Complementary evidence: A page may supply a useful fact, example, or qualification that other sources do not provide.
The important lesson is not to ignore organic rankings. Traditional SEO remains a valuable way to improve discoverability. Instead, businesses should recognise that AI citation visibility and conventional search rankings represent different outcomes.
Authority, Expertise, and Trust in AI Search
Authority is frequently discussed in relation to AI citations, but it should not be treated as a simple, universally measurable score.
A useful way to evaluate content is to consider whether its claims are supported, whether the publisher has relevant expertise, and whether other credible evidence agrees with it.
For example, a business publishing a guide to its own product should provide accurate specifications, practical instructions, and clearly identified limitations. If it publishes research, it should explain the methodology and distinguish measured results from opinions.
Similarly, an agency discussing campaign performance should provide meaningful context for its case studies, including the objective, period, methods, and relevant outcomes where disclosure is permitted.
Trustworthy content avoids exaggerated claims, makes important qualifications visible, and allows readers to verify the information.
These practices support credibility with human audiences and can improve the quality of the information available to search systems. They do not establish that any specific AI platform uses every one of these characteristics as an explicit ranking signal.
Step Four — Context Assembly and Answer Synthesis
Once relevant sources have been retrieved and selected, the system needs to transform the available information into a coherent response.
This is where context assembly and answer synthesis become central.
Context assembly determines which pieces of information are made available to the language model. Answer synthesis involves producing a response that explains the relevant material in a form suitable for the user.
How Retrieved Information Becomes Context
A retrieved webpage can contain thousands of words, but only a portion may be relevant to the question.
A system might therefore select particular passages, extract useful information, or otherwise prepare a smaller collection of evidence for answer generation.
For example, a webpage about e-commerce SEO might contain sections on:
- Technical site architecture.
- Product titles and descriptions.
- Image optimisation.
- Structured data.
- Internal linking.
- Conversion optimisation.
If the user’s question concerns product structured data, the section discussing product information and schema may be more useful than the rest of the page.
The selected material can then be supplied to the language model as part of the context used to formulate the response.
The details vary by system. Some implementations use passage retrieval, some use document-level context, and others may combine multiple retrieval or processing steps.
Why Context Quality Matters
The quality of the available context can influence the quality of the generated answer.
If the system retrieves reliable, relevant, and sufficiently detailed information, it has a stronger basis for producing a useful response. If the context contains outdated facts, missing qualifications, or contradictory claims, the model may struggle to provide a dependable answer.
Consider a question about the cost of an e-commerce platform.
One retrieved page might describe monthly subscription fees, another might discuss transaction fees, and a third might explain additional expenses for applications and payment processing.
If the response mentions only the subscription fee, it may understate the total cost. A more useful answer would distinguish the basic subscription from other potential expenses.
This illustrates why the context should contain the information needed to answer the question, not simply passages that share its keywords.
For content creators, it reinforces the importance of explaining important qualifications alongside the main claim.
Instead of writing:
“AI marketing tools reduce costs.”
A more useful explanation would be:
“AI marketing tools can reduce the time required for selected tasks, but the financial benefit depends on implementation costs, workflow integration, output quality, and the amount of human review required.”
The second statement provides context that makes the claim easier to interpret accurately.
How Large Language Models Synthesize an Answer
Large language models generate text by predicting sequences of tokens based on their learned parameters and the context provided to them.
When used in an AI search experience, a language model may receive a question together with retrieved information, instructions about the response format, and other contextual details.
It can then produce an answer that organises the relevant information into a coherent explanation.
For example, a user asks:
“How does AI search differ from traditional SEO?”
The retrieved sources may provide definitions of AI search, information about conventional search rankings, and examples of citation-based answers.
The language model can organise these details into sections explaining the differences in information retrieval, answer presentation, and measurement.
This is synthesis rather than simple copying. The model generates new wording to communicate information, although the degree of transformation varies by implementation.
The process also introduces risks. A model can misunderstand a source, omit an important qualification, or generate a statement that is not supported by the retrieved material.
Consequently, the presence of retrieved sources does not guarantee that every sentence in the final response is accurate.
How AI Search Handles Conflicting Information
Different webpages can provide conflicting figures, outdated information, or inconsistent interpretations.
Imagine three pages discussing the cost of a software product:
- One describes the monthly price from last year.
- Another lists the current annual subscription.
- A third describes a promotional rate available only to new customers.
A useful answer needs to distinguish these conditions rather than treating all three prices as interchangeable.
Depending on the system, conflict handling may involve comparing sources, prioritising particular evidence, retrieving additional information, or expressing uncertainty. The exact approach varies.
For businesses publishing information online, several practices can reduce avoidable ambiguity:
- Display publication and update dates where relevant.
- Identify the source and date of important statistics.
- Distinguish estimates from verified results.
- Explain the geographical or commercial scope of claims.
- Update outdated product details and service descriptions.
- Keep important facts consistent across related webpages.
These steps improve the usefulness of content even when an AI system does not explicitly evaluate them as separate signals.
Why Clear, Extractable Content Matters
Content structure affects how easily readers can find information and understand its relationships.
A well-structured article usually has a clear introduction, descriptive headings, focused paragraphs, and a logical progression from basic concepts to detailed explanations.
For example, a guide about AI search citations should not bury its definition of a citation halfway through a lengthy discussion of language models.
It should explain the concept early, clarify how citations differ from organic search results, and then explore the mechanisms and practical implications.
Useful content structures include:
- Direct definitions: Explain technical terms when they first appear.
- Question-led headings: Use headings that describe the information a section provides.
- Comparison tables: Present meaningful differences between related concepts.
- Step-by-step explanations: Describe processes in the order readers need to understand them.
- Evidence-backed examples: Demonstrate how a concept works in a realistic situation.
- Explicit qualifications: Explain where a claim applies and where it may not.
These techniques do not guarantee that an AI system will extract or cite a passage. Their value is that they make information more accessible, understandable, and useful.
Step Five — Citation: How AI Search Selects Sources to Reference
Generating an answer and citing its supporting sources are related but distinct tasks.
A language model can produce a fluent explanation without identifying the webpages that support each statement. An AI search system that provides citations must also associate relevant information with appropriate source references.
For businesses, this stage is particularly important because citations can create brand visibility even when users do not click through to the website.
What Are Citations in AI Search?
An AI search citation is a reference that directs users to a source associated with a generated answer.
Depending on the platform, citations may appear as clickable links beside a paragraph, numbered references, source cards, or a list of webpages accompanying the response.
Citations can serve several purposes:
- Help users verify factual claims.
- Provide access to more detailed information.
- Attribute information to publishers.
- Offer additional reading for complex questions.
- Give businesses and publishers visibility within AI-generated answers.
Citations should not automatically be interpreted as endorsements of an entire website. A system may cite a single passage because it supports one specific statement.
Likewise, a citation does not guarantee that the answer has represented the source accurately. Users may still need to open the original material to check context, dates, and qualifications.
How AI Search Systems Associate Claims With Sources
Consider an answer explaining three benefits of e-commerce product-page optimisation.
The system may retrieve one source about structured product data, another about page speed, and another about product descriptions.
To present useful references, it needs to associate the relevant claims with the appropriate sources.
Conceptually, this can involve several steps:
- Identify information used in the generated response.
- Determine which retrieved passages support the relevant statements.
- Associate those statements with suitable source references.
- Present the references in the answer interface.
The implementation can differ substantially across platforms. Some systems may maintain explicit links between generated content and retrieved passages, while others may use different source-attribution mechanisms.
It is therefore misleading to assume that every AI search engine uses one universal citation algorithm.
A useful distinction is between a source being available to the model and a source being displayed as a citation. A webpage might contribute background information without receiving a visible link, while another source may be cited because it directly supports a particular statement.
Why AI Search Cites Some Websites and Ignores Others
A page can be relevant to a topic without being selected as a citation.
Several possible explanations exist.
Direct relevance: A source may provide a particularly clear answer to the question or a specific sub-query.
Supporting evidence: A source may include verifiable data, original research, official documentation, or detailed examples that support the claim being made.
Source differentiation: A page may offer information that complements other retrieved sources rather than repeating their general explanations.
Accessibility: The relevant content may be available in a form that the system can retrieve and process.
Selection constraints: An answer may use only a subset of the available sources because of system design, response length, or other limitations.
Retrieval variation: Different queries, phrasings, locations, and times may produce different candidate sources.
These are plausible explanations for citation behaviour, not a complete description of the proprietary systems used by every AI search provider.
The practical lesson is to publish information that is genuinely useful and supports specific claims. A page that provides original evidence or a detailed explanation can offer something more distinctive than a generic article that repeats widely available information.
How to Improve the Chances of Being Cited by AI Search
There is no guaranteed method for securing AI citations. However, businesses can improve the discoverability and usefulness of their content by applying sound SEO and editorial practices.
1. Answer important questions directly. Introduce the main concept early and explain what it means before moving into more complex details.
2. Support claims with credible evidence. Use primary sources, official documentation, original research, and relevant expert analysis where available.
3. Add original value. Publish meaningful case studies, proprietary insights, demonstrations, or first-party data that help answer questions better than a generic explanation.
4. Improve content organisation. Use descriptive headings, logical sections, informative tables, and clearly written paragraphs.
5. Maintain technical accessibility. Ensure important pages can be crawled and indexed through the relevant search pathways, and avoid unnecessarily hiding essential information.
6. Keep factual details accurate. Review statistics, product specifications, prices, dates, and other information that may change.
7. Establish relevant topical coverage. Connect related guides through useful internal links and make the relationship between your core topics clear.
8. Build genuine reputation. Publish work that demonstrates expertise and seek legitimate recognition from relevant industry publications, partners, and professional communities.
These practices improve the overall quality of a website and support search visibility more broadly. They should not be presented as guaranteed citation factors or shortcuts to inclusion in AI answers.
AI Search Citations vs Traditional Backlinks
AI citations and backlinks both involve links between websites, but their purposes and contexts differ.
A traditional backlink is a link from one webpage to another. Backlinks can help users discover resources and are among the factors search engines may consider when evaluating websites.
An AI citation is a reference displayed in connection with a generated answer. It can direct a user to a page that supports a specific claim or part of the response.
| Feature | Traditional backlink | AI search citation |
| Context | A webpage links to another page | A generated answer references a source |
| Main purpose | Navigation, reference, or recommendation | Supporting or attributing information in an AI answer |
| How it appears | Within page content or site elements | Beside an answer, paragraph, or source list |
| Potential benefit | Referral traffic and possible SEO value | Brand exposure, referral traffic, and source visibility |
| Guaranteed ranking benefit | No | No |
| Relationship to content | Can exist independently of an AI answer | Usually associated with a particular generated response |
A website can earn backlinks without receiving AI citations, and it can receive AI citations without every cited page having a large backlink profile.
For this reason, marketers should track both conventional SEO performance and AI visibility where practical, rather than assuming that one measurement fully represents the other.
The Complete AI Answer-Generation Process: A Practical Example
Understanding individual components is useful, but the full process becomes easier to understand when applied to a realistic search query.
Consider a user asking:
“Which digital marketing agency in Dubai is suitable for an e-commerce business that wants to increase organic traffic and sales?”
The question combines a location, a service category, a business model, and two commercial objectives. A useful answer requires more than identifying webpages that contain the words “digital marketing agency Dubai”.
Depending on the platform, the AI search system may follow a process similar to the one below.
Stage One: Understand the Query
The system identifies the user’s primary objective: finding an agency that can support an e-commerce business.
It may identify several relevant criteria:
- Experience with e-commerce businesses.
- Expertise in technical and on-page SEO.
- Ability to improve product-page visibility.
- Conversion rate optimisation capabilities.
- Evidence of successful client projects.
- Availability of services in Dubai or the UAE.
These criteria represent possible information needs, not confirmed requirements that every user would have.
Stage Two: Expand the Query
The system may explore related questions to gather a broader set of information.
For example, it could investigate e-commerce SEO agencies in Dubai, agencies with relevant case studies, common e-commerce optimisation services, and evidence of campaign performance.
This is where query expansion or query fan-out may help identify sources that answer different aspects of the original question.
A platform might also answer the question through a simpler retrieval process. Not every query requires extensive expansion.
Stage Three: Retrieve Relevant Sources
The system searches its available information sources and identifies candidate webpages.
Potential sources might include agency service pages, e-commerce case studies, official business websites, independent industry publications, and other relevant material.
For example, an agency’s e-commerce SEO page may describe its technical services, while a case study may demonstrate how those services were applied to a particular project.
The system can only use information it can access through its available retrieval mechanisms. A website’s existence alone does not guarantee that it will be found.
Stage Four: Rank and Evaluate Candidate Information
The retrieved pages are assessed for their relevance to the information need.
An agency page that explains e-commerce SEO in detail may be more useful for evaluating technical expertise than a general page listing digital marketing services.
A case study containing a clear methodology and measurable results may provide more useful evidence than a page with unsupported promotional claims.
However, a reported improvement in organic traffic does not automatically prove that the same agency will achieve the same result for another business. The context and limitations of the evidence matter.
Stage Five: Assemble Context and Generate the Answer
The system uses selected information to construct a response that addresses the user’s requirements.
It may organise the response around relevant service capabilities, evidence of experience, and criteria for comparing agencies.
A well-grounded answer should distinguish verifiable facts from recommendations and should not invent client results, pricing, certifications, or service capabilities.
Stage Six: Associate Citations With Relevant Claims
Where the platform supports citations, it may provide links to agency websites, service pages, or case studies associated with particular statements.
A citation to an agency’s service page may support a description of its services. A case study may support a claim about a particular project, subject to the accuracy of the published information.
The presence of a citation does not establish that an agency is objectively the best choice. It shows that the source has been referenced in the answer.
What This Means for E-commerce Businesses and Agencies
A business that wants to appear in AI-powered search should provide information that helps potential customers evaluate its relevance.
An e-commerce agency, for example, can publish dedicated service pages, explain its methodology, document client work where permitted, and clarify which types of businesses it serves.
The goal is not simply to mention every possible search phrase. It is to create a credible body of information that answers the questions prospective customers are likely to ask.
The same principle applies to e-commerce retailers, software companies, professional service providers, and other businesses seeking visibility in AI-assisted discovery.
What AI Search Visibility Means for SEO, AEO, and GEO
The growing use of generated answers has encouraged marketers to reconsider how they define search visibility.
Traditional SEO remains important, but marketers are also paying attention to whether their content is used in direct answers, whether their brand is mentioned, and whether their webpages receive citations from AI-powered systems.
Three related concepts frequently appear in this discussion: Search Engine Optimisation (SEO), Answer Engine Optimisation (AEO), and Generative Engine Optimisation (GEO).
SEO: Building Search Discoverability
Search Engine Optimisation focuses on improving a website’s visibility in organic search results.
It includes several areas of work:
- Technical crawling and indexing.
- Information architecture and internal linking.
- Keyword and search-intent research.
- Content quality and relevance.
- Page experience and usability.
- Relevant authority and reputation signals.
These fundamentals remain useful in an AI search environment because many AI-powered discovery experiences draw on searchable web content or operate alongside traditional search results.
However, organic rankings alone do not reveal whether a page is being cited in a generated answer.
A business should continue to monitor conventional SEO metrics, including impressions, clicks, rankings, and organic conversions, while evaluating additional forms of search visibility.
AEO: Optimising Content to Answer Questions
Answer Engine Optimisation focuses on making content useful for systems and experiences that provide direct answers to user questions.
Practical AEO techniques include:
- Providing clear definitions.
- Answering common questions directly.
- Organising information with descriptive headings.
- Explaining technical concepts in accessible language.
- Supporting claims with evidence.
- Using structured data where it accurately represents the visible content.
For example, a page about retrieval-augmented generation can define RAG in its opening section, explain the process step by step, and discuss its limitations.
This structure helps readers understand the concept and makes the information easier to navigate.
AEO is not a single universally standardised technical specification. It is an umbrella term used by marketers for practices intended to improve the usefulness and accessibility of content in answer-oriented search experiences.
GEO: Optimising for Generative Search Experiences
Generative Engine Optimisation focuses on improving a brand’s visibility within AI-generated answers and other generative discovery experiences.
Depending on the context, this can include helping content become discoverable, improving the clarity of information about a brand, publishing original research, and creating useful resources that may be referenced in generated responses.
For example, a luxury retailer might publish detailed buying guides that explain product specifications, pricing considerations, authentication, and resale factors. These resources can serve users who are researching purchases and may also provide useful information for AI search systems.
However, GEO should not be reduced to writing content that attempts to please a language model. The stronger strategy is to improve the quality, relevance, credibility, and accessibility of the information available about a business and its subject matter.
SEO vs AEO vs GEO: What Is the Difference?
| Area | Primary focus | Example objective |
| SEO | Organic search visibility | Improve rankings and qualified organic traffic |
| AEO | Direct answers and answer-oriented experiences | Make information clear and useful for answering specific questions |
| GEO | Visibility in generative search experiences | Increase the likelihood of relevant brand mentions or citations |
| Shared foundation | Accessible, reliable, relevant information | Help users and search systems understand the content |
These approaches overlap. They should not necessarily be managed as completely separate disciplines.
A technically sound website with useful content can support SEO, AEO, and GEO simultaneously. The difference lies partly in the specific outcomes being measured.
Why Rankings Alone Are No Longer the Whole Picture
Imagine two websites competing in the same industry.
Website A ranks well for a broad commercial keyword but offers relatively limited supporting information.
Website B ranks lower for that particular query but has a detailed guide answering a narrower question that appears in an AI-generated response.
Depending on the search platform and query, Website B may receive a citation even though Website A has the stronger conventional ranking.
This does not mean Website B has better overall SEO or that citations are more valuable than rankings in every situation. It demonstrates that search visibility has several dimensions.
Marketers should distinguish between:
- Visibility in conventional organic search.
- Inclusion in AI-generated answers.
- Brand mentions without direct citations.
- Referral visits from AI platforms.
- Qualified leads and sales influenced by search discovery.
These measurements answer different questions and should be interpreted together.
How to Measure AI Search Performance
AI search reporting is still developing, and measurement options differ across platforms. A practical measurement framework should focus on observable outcomes rather than assuming that every citation or mention can be tracked perfectly.
AI citations: Record which relevant pages are cited for important customer questions when the platform makes that information visible.
Brand mentions: Monitor whether the business appears in AI-generated answers, including answers that do not contain a clickable link.
Referral traffic: Use available analytics reports to identify visits from AI search platforms where referrer information is preserved.
Organic search performance: Continue monitoring search impressions, clicks, rankings, and conversions through conventional SEO reporting.
Commercial outcomes: Measure enquiries, leads, assisted conversions, and sales where reliable attribution is possible.
Query coverage: Develop a consistent set of representative questions that reflect the business’s products, services, and audience needs.
For example, a Dubai-based digital marketing agency might track questions about e-commerce SEO services, local search optimisation, digital marketing costs, and industry-specific campaign strategies.
The team can periodically evaluate which sources appear in the answers and whether the agency’s own resources are being referenced.
AI responses can vary between queries and over time, so a single observation should not be treated as proof of a stable ranking or permanent citation position.
Practical Optimisation Checklist for AI Retrieval and Citation
Understanding AI search architecture is only useful if it leads to practical improvements.
The following checklist translates retrieval, ranking, synthesis, and citation into an actionable website optimisation strategy.
Technical SEO and Content Accessibility
Before investing heavily in new content, verify that search systems can access your important webpages.
Check crawling and indexing. Review robots directives, XML sitemaps, canonical tags, HTTP status codes, and relevant indexing reports.
Make important content accessible. Ensure that essential product information, service descriptions, and editorial content are available in a format that can be processed by relevant systems.
Use logical internal linking. Link related pages in ways that help users understand the relationship between subjects.
Avoid unnecessary duplication. Similar pages with overlapping purposes can make it harder to maintain a clear information architecture.
Maintain accurate metadata. Page titles and descriptions should represent the actual content rather than promising information that the page does not provide.
Implement structured data appropriately. Use relevant supported schema types when the page meets their requirements. Structured data can clarify information about products, organisations, articles, and other entities, but it does not guarantee AI citations.
Technical accessibility is a prerequisite for many discovery pathways, not a promise of visibility. A technically perfect page can still be irrelevant to a particular question.
Content Optimisation for Retrieval
Content optimisation should begin with the information the audience needs.
A useful workflow includes the following steps.
Step 1: Identify the primary question.
Decide exactly what the page should help readers understand or accomplish.
Step 2: Map related questions.
Identify the natural follow-up questions that belong within the article’s scope.
Step 3: Create a logical structure.
Organise the content from foundational explanations to detailed discussion, examples, and practical recommendations.
Step 4: Answer directly.
Introduce the main answer before adding supporting detail. Avoid making readers search through several paragraphs to find a basic definition.
Step 5: Add meaningful evidence.
Use official documentation, original data, relevant research, or clearly attributed expert perspectives to support important claims.
Step 6: Explain limitations.
Identify conditions under which a recommendation may not apply. This reduces ambiguity and makes the content more useful.
Step 7: Review for accuracy.
Check statistics, examples, terminology, and references before publication and update time-sensitive material when needed.
These practices can improve the quality and usefulness of content. They should not be confused with a technical formula that guarantees retrieval or citation.
Build Topical Authority With Related Content
A website can develop stronger subject coverage by publishing complementary resources around a clearly defined topic.
Suppose an agency wants to establish expertise in AI search optimisation. Its content cluster might include:
- How AI search engines generate answers.
- How query fan-out works in AI search.
- How large language models work.
- Training data versus live retrieval.
- AEO vs GEO vs LLMO.
- How AI citations differ from organic rankings.
- How businesses can measure AI search visibility.
Each article should have a distinct purpose. Internal links should help readers move between related topics when doing so provides genuine value.
For example, an article about AI citations can link to the retrieval guide when explaining why a source must first become available to the system.
A guide to query fan-out can link to the answer-generation article when discussing how multiple searches may contribute to a final response.
This creates a useful information network without requiring every article to repeat the same definitions.
Topical coverage alone does not guarantee search authority. The quality, accuracy, relevance, and usefulness of each resource remain important.
Strengthen Trust Through Evidence and Transparency
AI search optimisation should not become an excuse to publish exaggerated claims about how algorithms work.
If a business publishes research, it should explain its methodology. If it publishes case studies, it should provide sufficient context to interpret the reported outcomes. If it describes a product, it should keep specifications and pricing accurate.
For agencies and consultants, trust can be strengthened through:
- Clearly attributed expertise.
- Relevant examples of work.
- Transparent descriptions of services.
- Verifiable client outcomes where disclosure is permitted.
- Honest discussion of limitations.
- Consistent and accurate business information.
For e-commerce businesses, useful trust-building information may include detailed specifications, shipping policies, return conditions, product availability, and clear pricing.
These details help potential customers make informed decisions. They can also give search systems more complete information to draw upon when answering questions about the business.
A 30-Day AI Search Optimisation Plan
A short implementation plan can help a marketing team move from theory to action.
Days 1–7
Audit and establish a baseline
Review technical accessibility, important landing pages, current organic performance, existing brand mentions, and available AI referral data.
Days 8–14
Improve priority content
Rewrite unclear definitions, improve headings, add relevant evidence, correct outdated claims, and ensure important pages answer their intended questions.
Days 15–21
Develop connected resources
Identify content gaps, strengthen relevant internal links, and create supporting guides where they offer meaningful additional value.
Days 22–30
Measure and refine
Review a consistent set of target questions, inspect available AI citations and referral traffic, and prioritise the next round of improvements.
This plan is a starting point rather than a guaranteed timeline for improved AI visibility. Results depend on the website, competition, content quality, technical conditions, and how individual search platforms discover and use information.
Common Myths About AI Search Retrieval, Ranking, and Citation
Misunderstandings about AI search can lead businesses to invest in tactics that offer little practical value. Separating established principles from speculation is essential.
Myth 1: Ranking First Guarantees an AI Citation
A high organic ranking can improve discoverability, but it does not guarantee that a page will appear in a generated answer.
AI systems may use different retrieval processes, expand the original query, and select sources for specific sub-questions.
Practical takeaway: Continue investing in organic SEO while improving the relevance and usefulness of the content you want to be referenced.
Myth 2: AI Search Uses Only Highly Authoritative Websites
Reputation and reliability can matter when evaluating information, but a page’s usefulness also depends on the question.
A specialist source may provide a precise technical explanation that a broad publication does not cover.
Practical takeaway: Develop genuine expertise and provide relevant evidence rather than attempting to imitate the style of a large publisher.
Myth 3: FAQ Schema Guarantees Inclusion in AI Answers
Structured data can help eligible systems interpret particular kinds of information. However, adding FAQ schema does not guarantee that a page will receive an AI citation or appear as a direct answer.
Structured data must also follow the requirements of the relevant search platform.
Practical takeaway: Use schema accurately when appropriate, but prioritise the quality of the visible content and the needs of the reader.
Myth 4: Publishing More Content Automatically Improves AI Visibility
A large collection of repetitive articles can create maintenance problems without providing much additional value.
More pages do not necessarily mean better coverage, stronger authority, or more citations.
Practical takeaway: Prioritise useful, distinct resources that fill genuine information gaps. Consolidate overlapping content where necessary.
Myth 5: Every AI Search Engine Uses the Same Ranking Algorithm
AI search platforms differ in their retrieval systems, language models, source-selection mechanisms, and citation interfaces.
A tactic that appears useful in one platform may have a different effect in another.
Practical takeaway: Avoid universal claims about proprietary algorithms. Evaluate performance across the platforms and queries relevant to your audience.
Myth 6: AI Search Always Verifies Every Claim Against Multiple Sources
Some systems retrieve several sources, but this does not mean every statement is independently checked against multiple authoritative references.
An answer may rely on a limited source set, misinterpret a document, or contain unsupported information.
Practical takeaway: Verify important AI-generated claims against the original sources, especially when they involve financial decisions, legal obligations, health, or other consequential topics.
Myth 7: Adding More Keywords Makes Content Easier for AI to Cite
Keyword stuffing can reduce readability and make content repetitive. Semantic retrieval may identify related concepts even when the exact wording differs, but precise terminology remains useful when it clarifies the subject.
Practical takeaway: Use relevant terminology naturally and focus on explaining concepts, evidence, and relationships.
Myth 8: An AI Citation Guarantees Website Traffic
A citation can create an opportunity for a user to visit a website, but it does not guarantee a click, enquiry, or sale.
Some users may obtain enough information from the generated answer without opening the cited source.
Practical takeaway: Measure citations alongside referral traffic, qualified leads, conversions, and broader brand visibility.
Conclusion:
AI search engines introduce a new layer between discovering information and presenting it to users. Instead of simply returning a ranked list of webpages, AI-powered search experiences can interpret questions, retrieve information, prioritise sources, assemble context, synthesise answers, and display citations.
Understanding these stages helps explain why conventional organic rankings do not always predict which sources appear in AI-generated answers.
Retrieval determines which information becomes available for consideration. Ranking helps prioritise relevant sources. Context assembly organises information for the model, and answer synthesis transforms that information into a response. Citation mechanisms then associate the answer with supporting sources where the platform provides references.
Each stage creates different opportunities and limitations for businesses seeking search visibility.
For marketers, the practical response is not to chase an assumed secret AI ranking factor. It is to make information accessible, relevant, accurate, and useful. Publish content that answers real customer questions, support claims with credible evidence, build connected topic coverage, and maintain strong technical SEO fundamentals.
At the same time, measure AI visibility separately from conventional search performance. Citations, brand mentions, organic clicks, referral traffic, and conversions provide different perspectives on how people discover a business.
The central principle is simple: create information worth retrieving, content worth using, and evidence worth referencing. This approach supports a stronger foundation for SEO, AEO, and GEO without relying on guarantees about how proprietary AI search systems operate.
Frequently Asked Questions About AI Search Answers
1. How do AI search engines generate answers?
AI search engines may interpret a question, retrieve relevant information, rank candidate sources, assemble useful context, and use a language model to generate a response. Where supported, the system can associate citations with sources used in the answer. The exact process varies between platforms and queries.
2. What is the difference between retrieval and ranking in AI search?
Retrieval finds potentially relevant documents or passages from available information sources. Ranking prioritises those candidates according to their estimated usefulness or relevance. Retrieval determines what information can be considered, while ranking helps determine what is selected for further processing.
3. What is retrieval-augmented generation (RAG)?
Retrieval-augmented generation is an approach that combines external information retrieval with language-model generation. A system retrieves relevant documents or passages and provides them as context to help the model formulate a response. RAG can provide useful external evidence, but it does not automatically guarantee factual accuracy.
4. Why does AI search cite some websites but not others?
A website may be cited because it provides information relevant to a particular question, contains useful supporting evidence, or addresses a specific part of a broader query. Other relevant pages may not be retrieved or selected. Citation behaviour depends on the platform, query, available sources, and the system’s selection mechanisms.
5. Can a website rank low on Google but appear in an AI-generated answer?
Yes. Conventional organic rankings and AI source selection are not identical processes. A specialised page may answer a sub-question particularly well and be cited even when it does not rank highly for the original broad query. This outcome is possible, but it is not guaranteed.
6. How can businesses improve their chances of being cited by AI search engines?
Businesses can improve content accessibility, answer customer questions directly, publish evidence-backed information, maintain accurate facts, build relevant topical coverage, and strengthen their technical SEO. These practices can support discoverability and usefulness, but no method guarantees citation in a particular AI answer.
7. What is the difference between AI search citations and traditional backlinks?
A backlink is a link from one webpage to another. An AI search citation is a source reference associated with a generated answer. Both can help users discover information, but they appear in different contexts and have different measurement implications.
8. Does structured data help AI search engines retrieve website content?
Structured data can make supported information more explicit and machine-readable, and some search systems use it for particular features. However, its use varies across platforms, and adding schema does not guarantee retrieval, ranking, or citation. Structured data should accurately represent the visible page content.
9. How are SEO, AEO, and GEO related to AI search?
SEO focuses on organic search visibility, AEO focuses on making information useful for direct-answer experiences, and GEO focuses on visibility within generative search experiences. These approaches overlap through shared priorities such as technical accessibility, relevant content, and reliable information.
10. How can marketers measure AI search visibility?
Marketers can monitor citations, brand mentions, referral visits from AI platforms, organic search performance, and business outcomes such as enquiries and sales. A consistent set of relevant customer questions can help teams observe changes over time. Because AI responses vary, repeated observations are more useful than relying on a single result.
11. Does AI search use a website’s entire content or only selected passages?
The answer depends on the system. Some retrieval workflows identify particular passages or sections, while others may process documents at a broader level or combine several approaches. Making important information clear and well organised improves usability, but it does not guarantee that a specific passage will be selected.
12. How often should businesses update content for AI search?
Content should be reviewed according to how quickly its information changes and how important accuracy is to the reader. Pricing, product specifications, software features, regulations, and current statistics may require more frequent review than stable educational explanations. Updates should reflect meaningful changes rather than being made solely to alter a publication date.