How AI Chunks and Embeds Web Pages Before Choosing What to Quote
Why AI Search Looks Beyond the Entire Web Page
When a person searches for information, a search engine may present a list of relevant web pages. When an AI-powered search system answers a question, it may need to identify specific passages within those pages, compare information from multiple sources, and use selected material to construct a response. This makes the relationship between a web page and an individual passage important for modern search visibility.
Consider a website containing a 3,000-word article about artificial intelligence. The article explains web crawling, semantic search, vector embeddings, content chunking, retrieval-augmented generation, and AI citations. A user asks, “How do vector embeddings help AI find relevant website content?” The entire article may be relevant to the broad topic, but only a few paragraphs directly explain the answer.
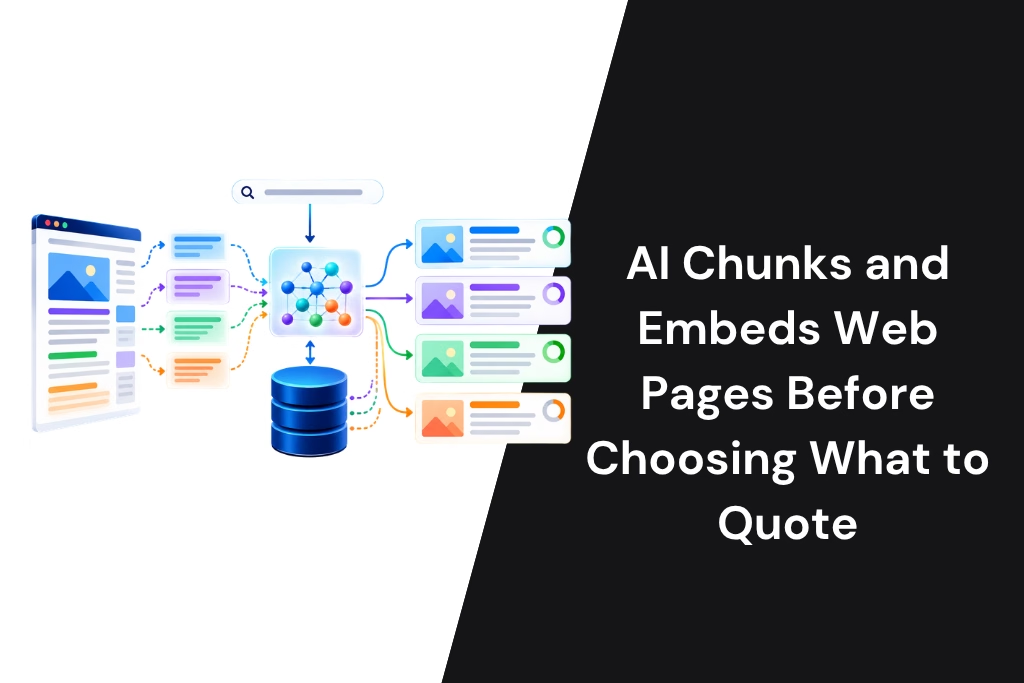
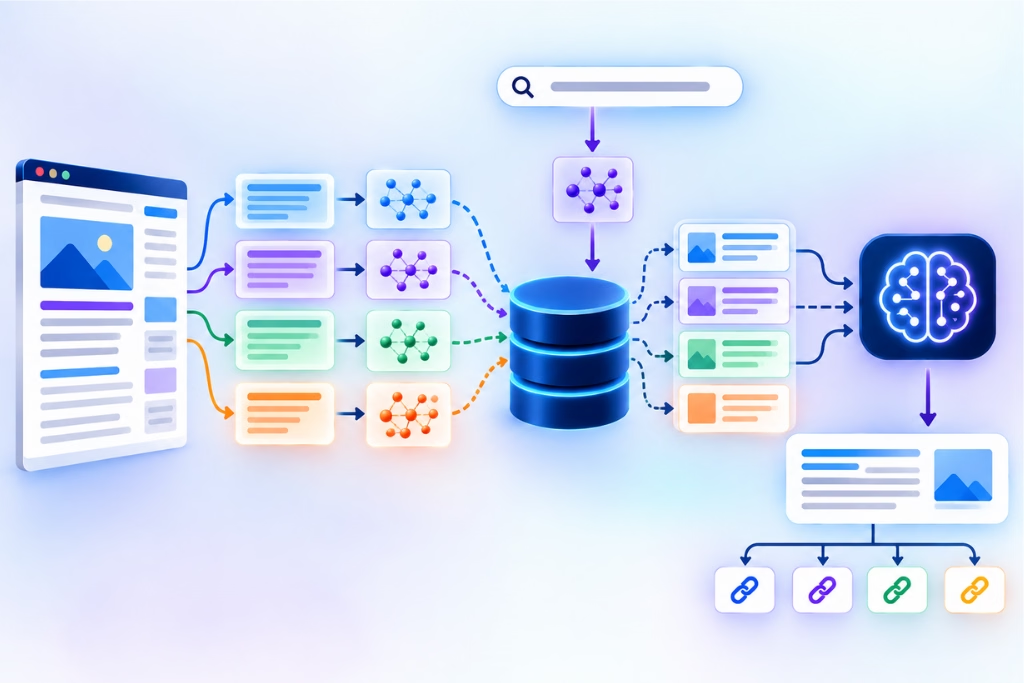
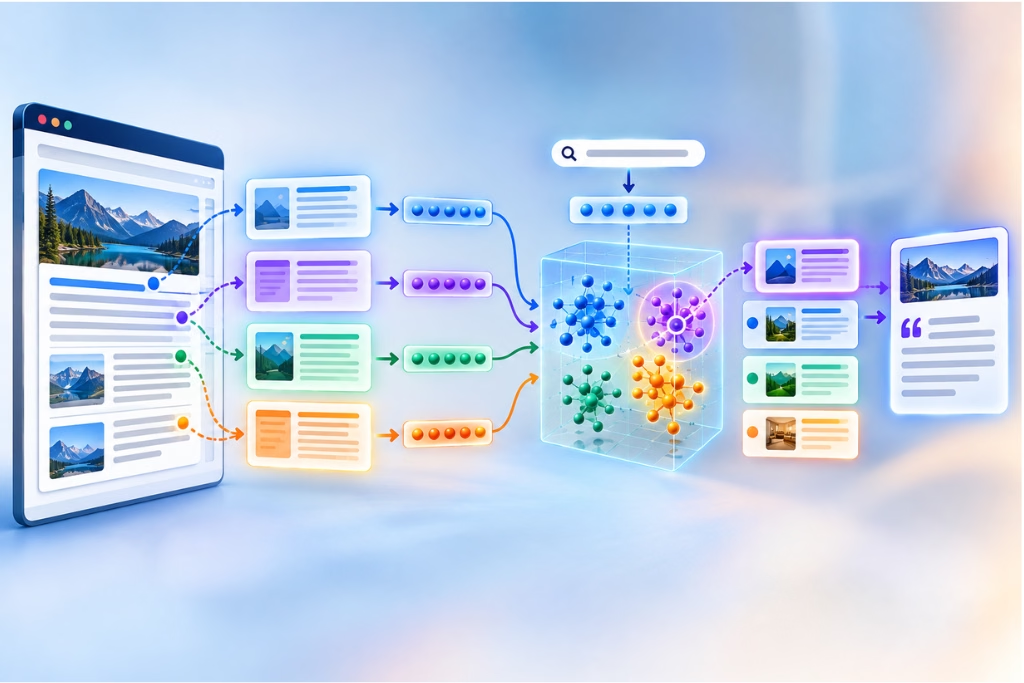
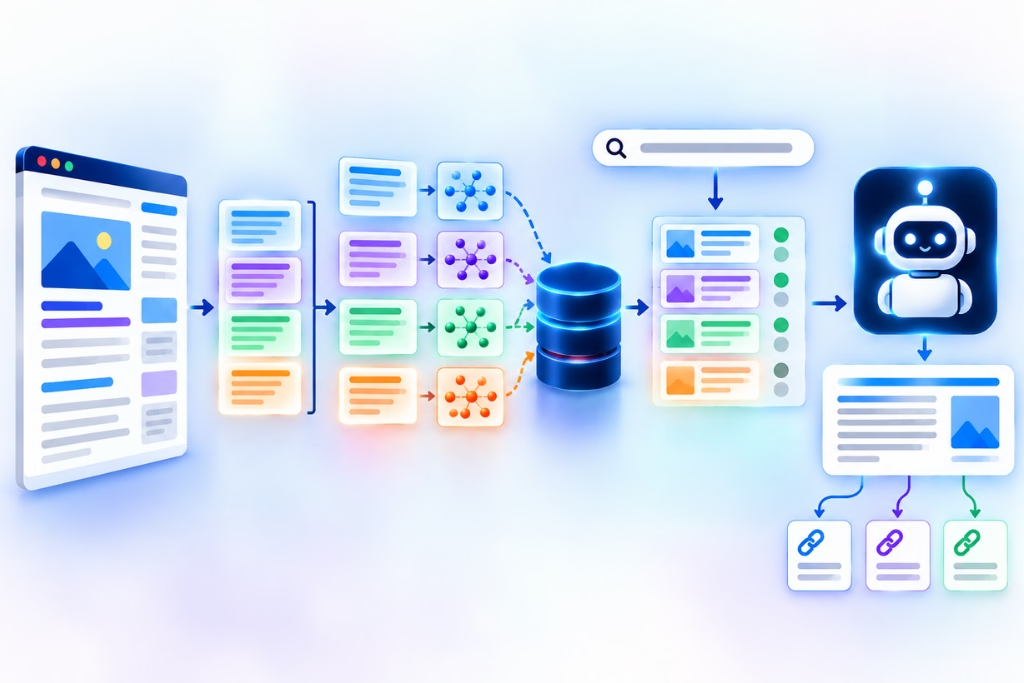
A retrieval system needs a way to identify those paragraphs. Depending on its architecture, it may extract the page’s text, divide the text into smaller units called chunks, convert those chunks into numerical representations called embeddings, and compare them with a representation of the user’s query. It may then rank candidate passages and supply selected material to a language model.
This process connects several important concepts: AI content chunking, vector embeddings in AI, semantic search optimization, passage retrieval, AI-powered information retrieval, and retrieval-augmented generation (RAG).
Understanding these concepts helps SEO professionals make content more accessible, coherent, and useful to retrieval systems. However, the precise mechanisms differ between platforms. A well-structured article can improve the clarity and usability of its information, but no particular heading format, paragraph length, or keyword placement guarantees that an AI system will quote or cite a page.
AI search systems may process website content by extracting readable text, dividing long pages into smaller passages called chunks, and converting those passages into numerical representations called vector embeddings. These embeddings help retrieval systems identify content that is semantically related to a user’s query, even when the wording differs. The system may then rank relevant passages using semantic similarity, keyword matching, source information, or other signals before providing selected content to a language model. In retrieval-augmented generation (RAG), the language model uses retrieved passages as context to generate an answer, summarize information, or support citations. Website owners can improve content clarity by using descriptive headings, writing self-contained paragraphs, answering specific questions directly, defining technical terms, and placing supporting evidence near relevant claims. Although these practices can make content easier to interpret and retrieve, they do not guarantee that an AI system will quote or cite a particular webpage, because retrieval and citation methods vary across platforms.
How AI Systems Obtain and Extract Web Content
Before an AI system can retrieve a passage from a web page, the relevant content must be available to its processing pipeline. That availability can depend on crawling, rendering, indexing, document ingestion, permissions, and the architecture of the particular service.
Not every AI product follows the same process. A web-connected answer engine may use an existing search index or retrieve current pages. An enterprise knowledge assistant may process documents uploaded by an organization. A website search application may index only a defined collection of URLs. These systems can share underlying concepts without using identical infrastructure.
Discovering the web page
In a web-search environment, discovery may begin when a crawler finds a URL through links, a sitemap, or another discovery mechanism. The crawler requests the page, subject to the service’s access policies and technical restrictions.
The page’s response matters. A successful response may provide the HTML document, while redirects, access restrictions, server errors, or blocked resources may prevent the intended content from being obtained. Canonical tags and internal linking can also influence how a website communicates its preferred URL and content relationships.
SEO teams should distinguish between a page being technically available and a page actually being indexed or used by a particular AI product. Accessibility is a prerequisite for many workflows, but it does not guarantee inclusion in an index or retrieval result.
Rendering and extracting the main content
A page’s HTML may contain the article alongside navigation menus, cookie notices, advertisements, sidebars, related posts, and footer links. A processing system may attempt to identify the main content and separate it from repeated interface elements.
JavaScript can complicate extraction when essential information appears only after a script runs. A page may look complete in a browser while the initial HTML response contains little of the main article. The behavior of individual crawlers and rendering systems varies, so critical information should be tested rather than assumed to be accessible.
For example, an article explaining vector similarity might display its central definition inside an interactive component. If the text is not exposed in a form the relevant processing system can access, that explanation may not be represented in the extracted content.
A practical response is to keep essential definitions, explanations, and factual claims in accessible text. Interactive diagrams and visualizations can add value, but they should not be the only place where the article communicates an important idea.
Preserving document structure
After extracting text, a system may preserve some information about headings, paragraphs, lists, tables, links, and metadata. How much structure survives depends on the extraction and indexing implementation.
That structure can matter because text is easier to interpret when its relationships are clear. A heading such as “How Vector Embeddings Support Semantic Search” provides context for the paragraphs that follow. A sentence extracted without its heading may still make sense, but it may lose useful information about the passage’s purpose.
For SEO, the objective is not to guess the exact HTML representation an AI system prefers. It is to make the source document clear and accessible to a broad range of users and processing systems.
Use a descriptive title, logical heading hierarchy, meaningful link text, accessible tables, and relevant image descriptions. Check that the extracted text preserves the intended reading order and that unrelated page elements do not overwhelm the main article.
How AI Divides Web Pages Into Chunks
Content chunking divides a larger document into smaller units that can be processed, stored, retrieved, or supplied to a language model. A chunk can contain a sentence, paragraph, group of paragraphs, subsection, or another span of text selected by the system.
The main purpose is to create manageable units of information. A long article may contain many topics, but a user query usually targets a narrower question. Chunking gives a retrieval pipeline the option to search for the relevant part instead of returning the entire document.
Why entire-page retrieval can be inefficient
Imagine a guide covering ten aspects of AI search. A user asks how tokenization affects the amount of text a model can process. Returning the entire guide could introduce unnecessary material about crawling, internal links, content marketing, and citations.
A smaller passage focused on tokenization can be more useful because it concentrates the relevant explanation. It may also consume less of the context budget when passed to a language model.
This does not mean that whole-document retrieval is never useful. Some tasks require broad context, such as summarizing an entire report or comparing arguments across a long document. A retrieval system may use passages for precise questions and larger document units for broader tasks.
The appropriate unit depends on the question, the document, and the system’s design.
Fixed-size chunking
Fixed-size chunking divides text according to a specified length. That length may be measured in tokens or another unit, and the implementation may use a configured overlap between adjacent chunks.
For example, a hypothetical system might create chunks containing approximately 400 tokens. A long article would be divided into consecutive segments, with each segment limited to roughly that size.
This method is predictable and relatively straightforward to implement. It can work well when documents have consistent structure or when a system needs uniform processing units.
However, fixed-size chunking does not inherently understand the meaning of a paragraph. A boundary might split a definition from its explanation or separate a claim from the qualification that makes it accurate.
Suppose a passage says:
“Embedding models convert text into numerical vectors. A retrieval system compares those vectors with a query representation to identify potentially relevant passages.”
If the split occurs between the two sentences, each chunk may still be understandable. But in a more complicated passage, a split could leave a sentence beginning with “This method” without the previous sentence that identifies the method.
The result is not necessarily unusable, but it may contain less context than the original text.
Sentence-based and paragraph-based chunking
Some chunking strategies respect sentence or paragraph boundaries. Instead of splitting text at an arbitrary point, they combine complete sentences or paragraphs until a length limit is reached.
This can preserve grammatical and conceptual units. For instance, a definition and its immediate explanation may remain together, reducing the likelihood that a passage begins or ends in the middle of an idea.
Paragraph-based chunking still has limitations. A paragraph may be extremely long, contain several distinct ideas, or depend on context elsewhere in the article. Conversely, a short paragraph may be too brief to explain a complex technical concept.
Writers should therefore use paragraphs to organize ideas naturally, rather than attempting to make every paragraph conform to a single presumed AI chunk size.
Semantic chunking
Semantic chunking attempts to create boundaries around meaningful content units. Depending on the implementation, a system may use headings, document structure, topic shifts, semantic similarity, or other rules to determine where one chunk should end and another should begin.
Consider a section that explains embeddings in three stages: what an embedding is, how a query can be represented, and how vectors can be compared. These ideas are closely related and may form a useful unit of explanation.
The next section might discuss how retrieved passages are supplied to a language model. That topic is related to embeddings, but it describes a different stage in the pipeline. Separating the sections can help preserve the distinction between representing text and generating an answer from retrieved content.
Semantic chunking is not a single standardized algorithm. Different implementations can produce different boundaries from the same document. Some systems use a hybrid approach that respects document structure while applying length constraints.
Chunk overlap and the preservation of context
Some systems allow adjacent chunks to overlap. Overlap means that a portion of text appears in more than one chunk, helping preserve continuity when a boundary falls between related statements.
For example, a chunk may end with a definition, while the next chunk begins with the final sentence of that definition and continues into an example. The repeated text can help preserve the connection between the concept and its explanation.
Overlap also has costs. It can increase storage and processing requirements, create duplicate retrieval results, and consume more context if multiple overlapping chunks are selected together.
The appropriate amount of overlap depends on the document, retrieval design, and downstream task. Website authors generally cannot set the overlap used by an external search engine. They can, however, write complete explanations and avoid unnecessary dependence on context located several paragraphs away.
Why chunk boundaries affect SEO indirectly
A chunk boundary can affect which information is available together during retrieval. If a section contains an important claim, its definition, supporting evidence, and qualification should be organized so that their relationship is clear.
For example, consider this weak passage:
“This approach can improve accuracy. It is widely used in modern systems.”
The passage does not identify the approach, explain the type of accuracy being discussed, or provide support for the broad claim.
A clearer version would be:
“Hybrid retrieval combines keyword-based matching with semantic retrieval in some search systems. The two methods can provide complementary signals, although their effectiveness depends on the query, the content collection, and the ranking implementation.”
The second passage identifies the technique, describes its role, and acknowledges that results depend on the implementation. It remains informative even if separated from the surrounding article.
This is the practical connection between chunking and SEO: authors cannot control an external system’s segmentation rules, but they can make the original content less ambiguous and more useful when read in smaller units.
How Embedding Models Convert Text Into Numerical Representations
After text has been prepared for semantic retrieval, an embedding model may convert each chunk into a numerical vector. The vector represents the text in a learned mathematical space, enabling a system to compare the chunk with a query or with other content.
This is the central mechanism behind many forms of vector search and semantic search optimization.
What is a vector embedding?
A vector is an ordered collection of numbers. An embedding model produces a vector from text according to patterns learned during training. Depending on the model, the vector may have hundreds or thousands of dimensions.
Those dimensions are not normally a set of simple human-readable categories. It would be misleading to assume that one dimension always represents “SEO” and another always represents “trust.” Meaning is distributed across the learned representation.
The important property is that the model can represent relationships between text inputs in a way that supports downstream tasks. Texts that are related under the model’s learned representation may have vectors that are close according to the similarity measure used by the system.
The exact behavior depends on the model, its training, the input format, and the retrieval setup.
How a passage becomes an embedding
Suppose an article contains the following passage:
“Content chunking divides long documents into smaller text units so a retrieval system can locate relevant sections.”
An embedding model processes the text and returns a vector. During indexing, the system may store that vector alongside the original text, a document identifier, the page URL, and other metadata.
When a user later asks, “How does AI find the right part of a long article?”, the system may generate a vector for the query using a compatible embedding model. It can then compare the query vector with the stored passage vectors.
The query and passage do not need to share every word for a relationship to be detected. The model may recognize that “find the right part” is conceptually related to locating relevant sections.
This is one advantage of semantic retrieval over exact keyword matching alone. It can help find relevant content when users phrase a question differently from the wording used by the author.
How similarity is calculated
A retrieval system needs a method to compare vectors. One common option is cosine similarity, which compares the angle between two vectors. Other implementations may use dot products, Euclidean distance, or methods appropriate to the model and indexing system.
In a simplified example, imagine three passages:
- Passage A explains how documents are divided into chunks.
- Passage B explains how vector embeddings represent text.
- Passage C describes how a website’s navigation menu works.
For a question about chunking long documents, Passage A may be the most relevant candidate. Passage B might be related to the broader retrieval process, while Passage C is likely less relevant.
The system’s similarity scores can help identify candidates, but those scores should not be treated as direct probabilities that a passage is correct or will be quoted. A high similarity score means the passage compares favorably under the chosen method, not that it has been independently verified.
Why semantic similarity is not factual verification
Two passages can be semantically similar while differing in accuracy. One may contain a supported explanation; another may contain a misleading claim about the same subject.
For example:
“Some retrieval systems combine keyword search and vector search.”
“Every AI search engine uses the same hybrid retrieval architecture.”
Both passages concern retrieval architecture, but the second makes an unsupported universal claim. Semantic similarity alone cannot establish which claim is true.
A retrieval pipeline may incorporate other signals, such as ranking models, metadata, source selection, or validation processes. The exact combination varies by application.
For content creators, the lesson is simple: do not optimize solely for conceptual similarity. Publish accurate explanations, distinguish evidence from inference, and make the scope of technical claims clear.
Embedding models and query-document compatibility
A retrieval system typically needs a compatible way to represent queries and documents. Some models are designed for related query and document inputs, while other architectures use separate encoders or task-specific formatting.
The quality of retrieval can depend on this compatibility. A vector database by itself does not guarantee meaningful search results; the embedding model, text preparation, indexing configuration, similarity method, and retrieval strategy all matter.
Website owners usually do not control these internal choices in an external AI search product. Their role is to provide useful source material with clear language and meaningful topic coverage.
How Vector Databases and Search Indexes Find Candidate Passages
Generating embeddings is only part of the process. A system also needs a way to store and search them.
A vector database or vector index can store numerical representations and support similarity search across a collection of passages. In a production system, the vectors may be accompanied by text, URLs, document IDs, timestamps, access controls, and other metadata. Some systems use specialized vector databases; others integrate vector retrieval into broader search infrastructure.
Storing the chunks and their metadata
Imagine a company has indexed 50,000 help-center passages. Each passage may have an embedding, its source URL, a title, a heading path, a publication date, and an access-control label.
When a query arrives, the system can search the vector index for related passages. The metadata can help the application identify the original source, filter results, enforce permissions, or present a citation.
For public website search, source metadata can help connect a retrieved passage to its original page. However, the presence of metadata does not guarantee that the final answer will display a citation. Citation display depends on the application’s design and source-handling process.
Approximate nearest-neighbor search
Large collections can contain millions of vectors. Comparing a query vector with every stored vector may be expensive, so some systems use indexing methods that quickly identify approximate nearest neighbors.
Approximate nearest-neighbor search trades exhaustive comparison for efficiency. Depending on the index and configuration, it can retrieve likely candidates without calculating an exact comparison against every vector.
This is an implementation detail that matters to search-system designers, but it should not be turned into a website optimization rule. Publishing more keywords or using shorter paragraphs does not directly configure an external vector index.
The SEO-relevant point is that a retrieval system needs to find candidate content efficiently. Clear, focused passages give the system useful material to evaluate once those passages are available to its search pipeline.
Metadata filters and source constraints
A retrieval system may apply filters before or after similarity search. These filters can restrict results to a particular document collection, language, date range, content type, or access level.
For example, a support assistant might retrieve only from the latest approved product documentation. A company knowledge assistant may exclude documents that a user is not authorized to access.
In web search, source availability and product policies can also influence which pages are eligible to appear. These rules differ by service and cannot be inferred from embeddings alone.
This is why content quality and technical access must be considered together. A well-written passage cannot be retrieved if it is unavailable to the system, and an accessible passage may not be selected if it is irrelevant to the query.
How AI Retrieves and Ranks Relevant Passages
Once a system has a searchable collection of content, it can identify candidate passages for a user’s question. This process is commonly described as retrieval. Many systems combine several methods because different methods capture different aspects of relevance.
Query interpretation and expansion
A user might ask, “How can I make a website easier for AI to quote?” The question may imply several related concerns: whether the page is accessible, whether the relevant information is easy to retrieve, whether the content answers a specific question, and whether the answer can be attributed to a source.
Some systems may transform the query, generate related searches, or break a complex question into subquestions. Others may retrieve directly from the original wording. These query-processing methods are system-dependent.
For content strategy, this means that understanding the user’s intent matters more than mechanically repeating the question. An article should explain the core concept and address the relevant follow-up questions that naturally arise from it.
Keyword retrieval and semantic retrieval
Keyword-based retrieval looks for lexical matches between a query and documents. It can be especially useful for exact product names, identifiers, specialized terms, or phrases that must match closely.
Semantic retrieval uses learned representations to identify related content even when the wording differs. It can help connect “divide a long document into sections” with “text chunking,” for example.
Some search systems combine lexical and semantic methods. This is often called hybrid retrieval. The system may merge or rerank results from multiple retrieval approaches to improve the candidate set.
Neither method is universally sufficient. Keyword matching can miss a relevant passage with different wording, while semantic similarity can retrieve a passage that discusses the same concept without answering the exact question.
Reranking candidate passages
The first retrieval stage may return more candidates than the application ultimately needs. A reranking model can evaluate those candidates more closely against the query and reorder them.
For example, a semantic search might return passages about embeddings, vector databases, and AI content optimization. A reranker may prioritize the passage that directly explains how a query vector is compared with stored passage vectors.
Reranking is not universal, and its implementation varies. Some systems may use multiple ranking stages or additional source-level signals. External website owners generally cannot know the complete ranking process for a proprietary service.
The actionable lesson is to make the relationship between a section and its intended question explicit. A focused explanation is easier to evaluate for relevance than a paragraph that mentions many concepts without fully explaining any of them.
Relevance, completeness, and evidence
A passage can match the topic but still fail to answer the question completely. If someone asks how embeddings help retrieve content, a sentence that merely defines embeddings may be relevant but incomplete. A more useful passage explains that embeddings represent text as vectors and that retrieval can compare query and passage representations.
Evidence also matters. A technical claim supported by reliable documentation is more defensible than an unsupported assertion. Some systems may use source quality or freshness signals, but there is no universal public formula that explains how every AI system evaluates these characteristics.
For authors, the goal should be to make the passage accurate, relevant, and sufficiently complete—not to guess a secret ranking formula.
How Retrieved Passages Become AI-Generated Answers
Retrieval and generation are related but separate processes. A passage can be retrieved without being quoted, and a passage that influences an answer may be paraphrased rather than reproduced verbatim.
In retrieval-augmented generation, selected passages are supplied to a language model as additional context. The model uses the query, the provided material, and its instructions to generate a response. The application may preserve source metadata so that citations or source links can be shown.
Building the context for the model
Imagine a user asks, “What is the difference between fixed-size chunking and semantic chunking?”
The retrieval system might select one passage explaining fixed-size segmentation and another explaining semantic boundaries. Those passages can be included in the model’s context alongside the user’s question and instructions.
The model can then compare the approaches and explain their differences. If the retrieved material is incomplete, contradictory, or unclear, the generated answer may also be incomplete or misleading.
Context limits can affect how much material an application supplies. The system may need to select a subset of retrieved passages, summarize information, or prioritize certain documents. The specific approach depends on the product.
Why self-contained passages help
Consider two possible passages.
Passage A: “This can improve accuracy, but it depends on the approach.”
Passage B: “Semantic chunking can preserve the relationship between a heading and its explanation. This may help a retrieval system evaluate a passage with more context, although the outcome depends on the system’s implementation.”
Passage B provides more usable context. It identifies the technique, describes the mechanism, and includes a qualification. A language model can interpret it without needing to infer as much from missing sentences.
Self-contained writing does not require every paragraph to repeat the entire article. It means that the key subject and relationship remain clear when a section is read separately.
Why the model may paraphrase instead of quoting
An AI-generated answer may summarize a source, combine information from several passages, or respond in its own words. A product may display citations beside the answer, attach sources to specific statements, or provide a separate source list.
Whether a system quotes verbatim depends on its generation behavior, instructions, citation design, and the nature of the query. It is not possible to guarantee a direct quotation simply by formatting a passage in a particular way.
This distinction is important for SEO measurement. Being crawled, indexed, retrieved, used as context, quoted, and cited are different outcomes. A page may achieve one without achieving all the others.
What Makes a Passage More Useful for AI Retrieval?
There is no universal passage formula that guarantees selection across AI search products. However, several editorial characteristics make information clearer and more useful for readers and systems that process text in smaller units.
Direct answers
Start the relevant section with a clear answer to its central question. If the heading asks how embeddings support retrieval, explain the relationship between vector representations and similarity search before moving into background details.
A direct answer reduces the effort required to identify the section’s main point. It also gives the rest of the passage a clear purpose.
Explicit entities and relationships
Use the names of the concepts being discussed instead of relying on vague references. “A vector database stores embeddings for similarity search” is more explicit than “It stores them so they can be compared.”
Semantic triples can help writers think through the relationships in a sentence: a subject performs an action on an object, or one concept affects another under specific conditions. For example, “An embedding model converts text into a numerical vector” clearly identifies the model, the action, and the result.
This is not a rigid writing formula. Natural language can express complex relationships in many ways. The objective is to make the intended meaning easy to follow.
Definitions, mechanisms, and examples
A useful technical explanation often includes three elements: what a concept is, how it works, and why it matters.
For instance, a section on chunk overlap should define overlap, explain how adjacent chunks may share text, and discuss the trade-off between preserving context and increasing redundancy.
Examples make the mechanism concrete. They also reveal gaps in an explanation: if a writer cannot provide a clear example, the concept may need further development.
Accurate qualifications
Avoid absolute claims about systems whose internal behavior is unknown. Statements such as “AI always prefers short paragraphs” or “Every AI search engine uses vector databases” are too broad.
Prefer qualified explanations: “Some retrieval systems use vector indexes to identify semantically related passages, while others combine vector search with lexical retrieval or use different architectures.”
Qualifications do not weaken an article when they reflect genuine uncertainty. They help readers distinguish established mechanisms from implementation-specific details.
Evidence and attribution
When a passage contains statistics, quotations, technical claims, or product-specific descriptions, link to a source that supports the statement. Prefer primary research, official documentation, recognized standards, and credible original reporting where relevant.
Do not invent expert quotations or imply that a hypothetical example is a measured result. If a statement is a recommendation rather than a demonstrated outcome, label it accordingly.
Evidence helps readers assess reliability and can make the content more valuable to applications that prioritize source quality. It does not, by itself, guarantee that an AI system will select or cite the passage.
A Practical Example: From One Web Page to a Potentially Retrieved Passage
Consider a hypothetical article titled “A Guide to AI Search for Website Owners.” The page covers crawling, content chunking, embeddings, vector search, RAG, and AI citations.
A user asks: “How do vector embeddings help AI find the right section of a web page?”
The following sequence illustrates one possible retrieval workflow. It is an explanatory example, not a claim that every AI search engine uses these exact steps.
Step 1: The page becomes available. A crawler or ingestion pipeline obtains the page and extracts the main text.
Step 2: The document is segmented. The pipeline divides the article into chunks. One chunk explains embeddings, another describes vector similarity, and a third discusses AI citations.
Step 3: The chunks are represented. An embedding model converts the selected text units into numerical vectors. The system stores the vectors with the corresponding text and source information.
Step 4: The query is processed. The user’s question is represented in a form compatible with the retrieval system. The system searches for passages that may answer the question.
Step 5: Candidate passages are ranked. The passage explaining vector similarity may be more directly relevant than the passage about citations. The system may use semantic similarity, lexical matching, reranking, metadata, or other signals.
Step 6: Selected passages enter the answer context. If the application uses retrieval-augmented generation, it may provide the chosen passage to the language model along with the user’s question.
Step 7: The answer is generated. The model may explain the concept in its own words, quote a passage, or combine multiple sources. The product may display a citation if its source-handling process supports one.
The practical lesson is that a useful passage needs to survive several distinct stages. Technical accessibility makes the content available; coherent chunking preserves meaning; embeddings can support semantic matching; ranking helps select candidates; and generation determines how retrieved information is used.
Website owners influence some parts of this process through content quality and technical implementation, but they do not control every downstream decision.
How to Optimize Website Content for AI Retrieval
An effective optimization process combines technical accessibility, strong information architecture, useful writing, and careful measurement.
Audit crawlability and rendering
Check whether important pages return the expected status codes, use appropriate canonical URLs, and can be accessed by the relevant crawlers under the applicable policies. Review robots directives and access restrictions where relevant.
If the article relies on JavaScript, test whether its main content is available to the processing systems that matter. Do not assume that every AI product uses the same crawler or rendering process.
Improve headings and section boundaries
Give every major section a clear purpose. Use descriptive headings that identify the concept or question being addressed. Avoid headings that promise one topic but introduce several unrelated subjects.
For example, a section titled “How Vector Similarity Search Works” should explain vector comparison and candidate retrieval. A separate section can discuss how retrieved passages are supplied to a language model.
This structure helps readers navigate the page and makes the relationship between topics more explicit.
Keep related information together
Place definitions near the explanations that depend on them. Keep important qualifications close to the claims they modify. Introduce examples after explaining the concept they illustrate.
If a passage contains a statistic, preserve the source and relevant context so the statistic does not become misleading when extracted. If a sentence depends on a previous paragraph, consider revising it so that the reference is clear.
Cover related questions without keyword stuffing
Use the primary keyword, embeddings SEO, naturally in the title, introduction, and relevant sections. Include related concepts such as semantic search, AI content chunking, vector similarity search, and passage retrieval when they contribute meaningfully to the explanation.
Do not generate hundreds of near-duplicate keyword variations merely to make the article appear semantically comprehensive. Useful topical coverage comes from explaining relationships, answering realistic questions, and resolving the reader’s uncertainty.
Strengthen internal and external references
Link to relevant internal guides about AI search, RAG, query fan-out, and indexing. Use descriptive anchor text and ensure that the destination provides the information the link promises.
For external references, prioritize sources that directly support technical claims. Official documentation and original research are especially useful when explaining specific implementations. Distinguish between what a source documents and what you infer from it.
Measure what can actually be observed
Track conventional search performance through impressions, clicks, rankings, and click-through rates. Where reliable tools expose AI citations or referral traffic, monitor those signals separately.
Use a consistent measurement period and record content changes. Avoid claiming that a change in chunk structure caused an increase in AI citations unless the available evidence supports that conclusion.
A useful test is to create realistic questions that the article should answer. For each question, identify the best passage and check whether that passage is accurate, complete, and easy to understand without the entire article. This editorial test does not replicate a proprietary AI retrieval system, but it can reveal content gaps.
Common Misconceptions About Chunking, Embeddings, and SEO
Misconception 1: Every AI search engine uses the same chunk size
Chunking methods differ by system, task, document type, and implementation. A chunk length that works well in one RAG application may not be used by a public search engine.
Better approach: Write coherent sections and complete explanations rather than optimizing for an assumed universal token limit.
Misconception 2: Embeddings understand truth
Embeddings represent learned relationships in text. Similarity can help identify related passages, but it does not independently verify whether a claim is accurate.
Better approach: Use reliable evidence, precise wording, and clear qualifications.
Misconception 3: More keywords produce better embeddings
Keyword repetition does not guarantee better semantic retrieval. Repetitive content can make an article harder to read and can distract from the actual answer.
Better approach: Cover the relevant concepts naturally and explain how they relate to the main subject.
Misconception 4: A retrieved passage will be quoted
Retrieval identifies potentially useful content. The generation system may paraphrase it, combine it with other sources, omit it from the final response, or display a citation according to product-specific rules.
Better approach: Improve relevance, clarity, and evidence while recognizing that citation decisions remain outside the website owner’s control.
Misconception 5: Short paragraphs are always better
Short paragraphs can improve scanning, but a paragraph that is too short may lack context. A longer paragraph may be appropriate when it explains one connected technical idea.
Better approach: Organize around meaning rather than a fixed paragraph length.
Conclusion: Make Every Important Passage Clear, Useful, and Defensible
AI systems can process web content through several stages: obtaining a page, extracting its main text, dividing the text into chunks, representing passages with embeddings, retrieving candidates, ranking relevant material, and using selected content to generate an answer. Some systems combine these stages differently, and the details are not universal.
For SEO professionals, the most practical strategy is to make the information clear at every level. Ensure that important content is technically accessible. Use descriptive headings and logical sections. Explain technical terms explicitly. Keep definitions, evidence, and qualifications close to the claims they support. Write passages that remain understandable when read outside the complete article.
These practices cannot guarantee a quotation or citation, but they can make website content more useful to readers and to systems that retrieve and process information. That is the durable objective of embeddings SEO: not to manipulate an unknown algorithm, but to publish accurate, accessible, well-structured information that directly answers the questions an audience needs to resolve.
FAQ
1. How does AI chunk web pages before searching them?
A system may extract a page’s text and divide it into smaller units using token limits, sentence or paragraph boundaries, document headings, semantic boundaries, or a combination of techniques. The resulting chunks can be stored and retrieved independently. The exact method varies by system.
2. How do vector embeddings help AI retrieve website content?
Embedding models convert text into numerical vectors that can be compared using a similarity or distance measure. A retrieval system can use those comparisons to identify passages related to a query, even when the wording differs. Similarity does not establish factual accuracy.
3. What makes a web page easier for AI to quote?
Clear, accessible content helps. Use descriptive headings, answer specific questions directly, explain entities and relationships, keep related claims and qualifications together, and support factual statements with reliable sources. These practices improve clarity but cannot guarantee a quote or citation.
4. Does chunk size affect AI search accuracy?
It can affect the amount of context available in a retrieved passage. Very small chunks may lose important relationships, while very large chunks may combine unrelated topics. The best approach depends on the document and retrieval system, so no single size is universally optimal.
5. Is embeddings SEO different from traditional SEO?
Embeddings SEO emphasizes how semantic representations and passage retrieval can help systems find conceptually relevant content. It complements rather than replaces technical SEO, useful content, clear information architecture, and search-intent alignment. The actual influence of embeddings depends on the retrieval system being used.